Running and Managing Kubeflow Pipeline Runs
Execute, Schedule, Monitor, and Troubleshoot Parameterized Machine Learning Pipelines Using the Kubeflow UI and Python SDK
By Sandip Das · · 10 min read
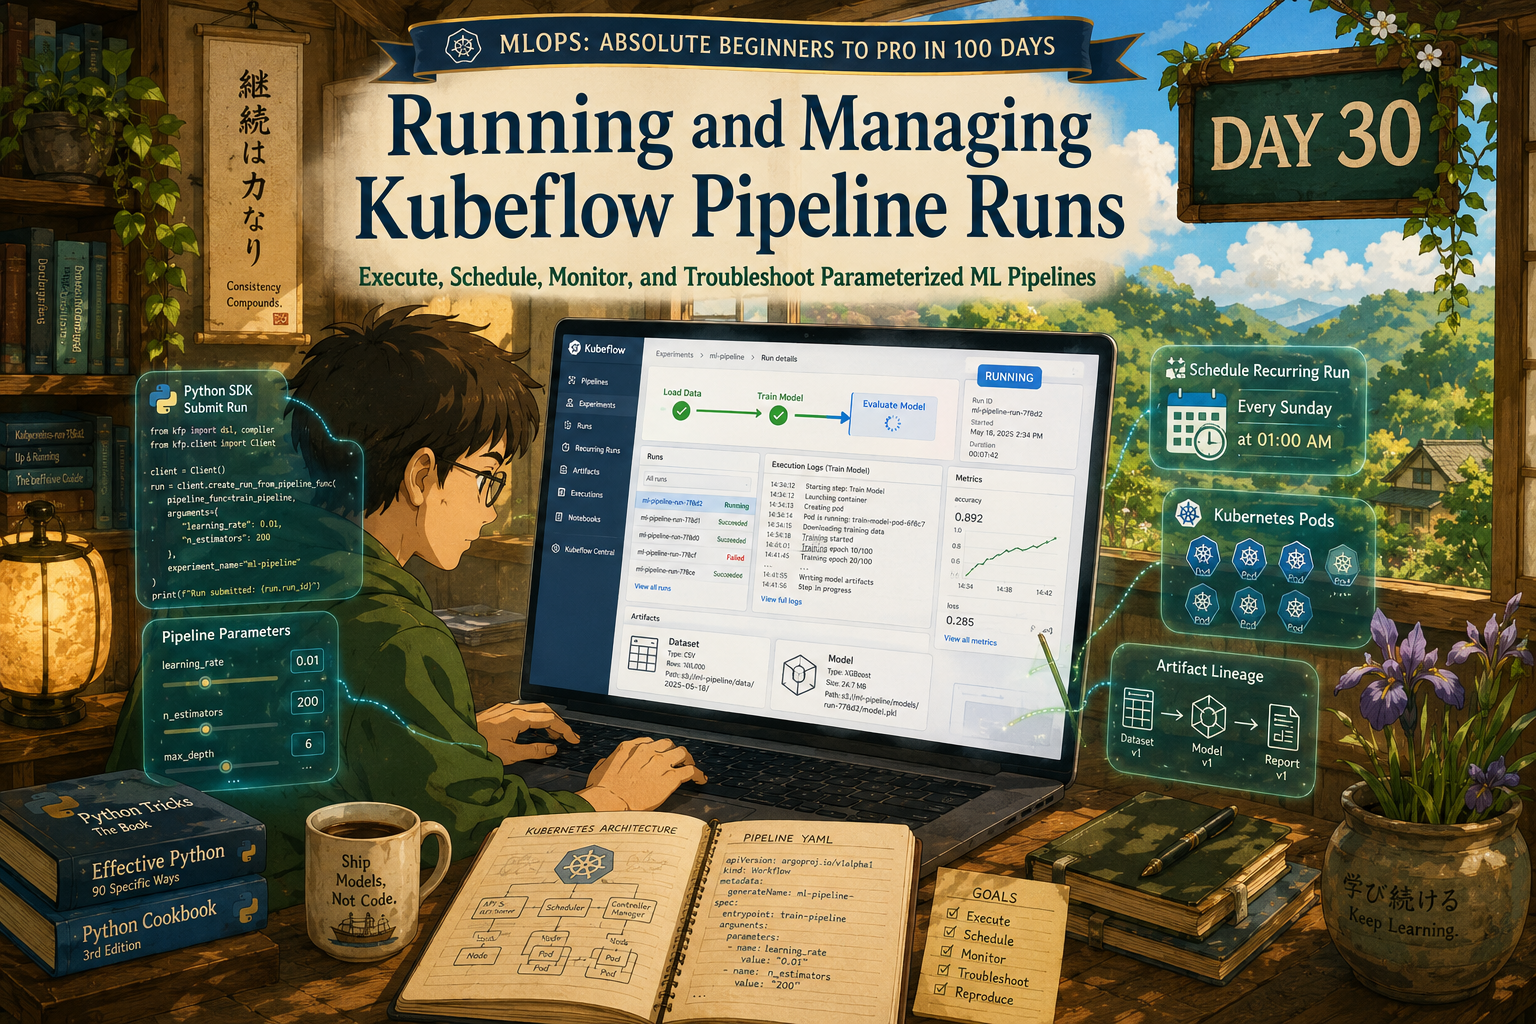
💡
Hey — It's Sandip Das 👋
We should learn Kubeflow run management to reliably execute, schedule, monitor, and troubleshoot parameterized ML pipelines at scale.
It enables repeatable automation, artifact tracking, and faster operational control across the complete machine-learning lifecycle.
We should learn Kubeflow run management to reliably execute, schedule, monitor, and troubleshoot parameterized ML pipelines at scale.
It enables repeatable automation, artifact tracking, and faster operational control across the complete machine-learning lifecycle.
📚 Key Learnings
- Trigger a pipeline run from the Kubeflow UI and from the Python SDK
- Pass hyperparameters as run parameters instead of hardcoding them
- Launch a small hyperparameter sweep as parallel runs and wait for all of them
- Schedule a recurring retraining run with cron, concurrency, and catchup control
- Read run status, logs, metrics, and output artifacts programmatically
🧠 Learn here
You compiled a pipeline yesterday. Today you turn it into something that executes on demand, on a schedule, with di
Read the full article on learnxops.com.
Topics: 100 Days of MLOps, MLOps, ML, Kubernetes, Kubeflow