Building Kubeflow Pipelines with the Python SDK
Build, Connect, Compile, and Deploy Reusable Machine Learning Pipelines Using the Kubeflow Python SDK
By Sandip Das · · 20 min read
💡
Hey — It's Sandip Das 👋
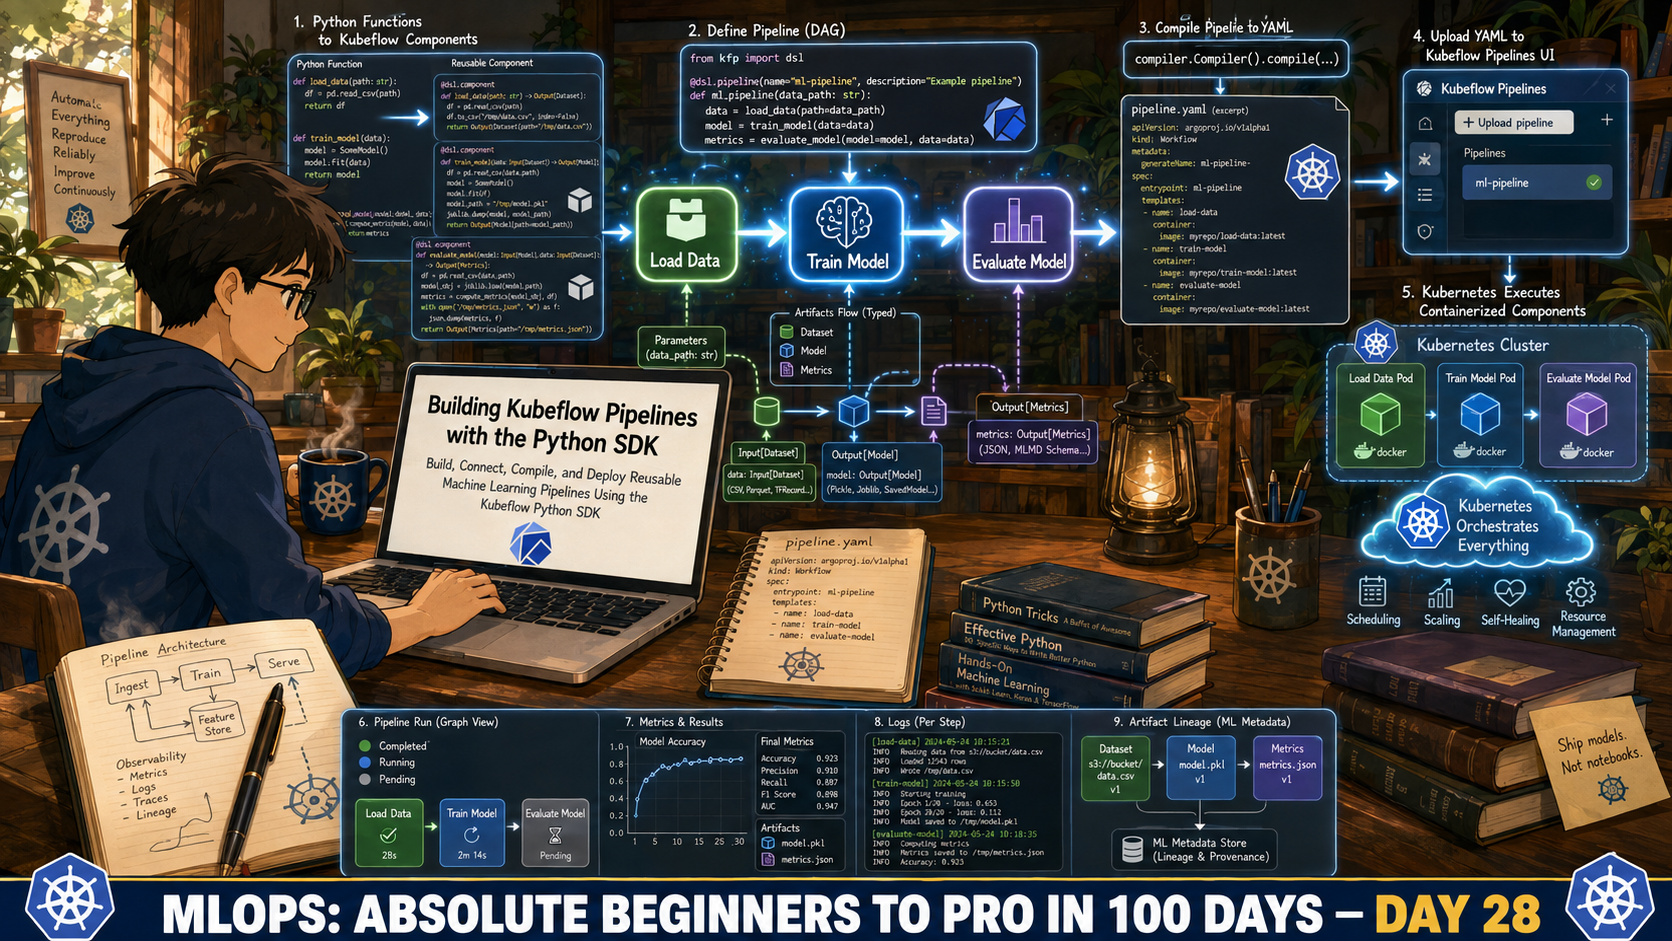
Learn the Kubeflow Python SDK to transform machine learning workflows into reusable, scalable, and reproducible pipeline components.
It enables them to automate data preparation, model training, and evaluation while managing artifacts, parameters, and execution seamlessly on Kubernetes.
Learn the Kubeflow Python SDK to transform machine learning workflows into reusable, scalable, and reproducible pipeline components.
It enables them to automate data preparation, model training, and evaluation while managing artifacts, parameters, and execution seamlessly on Kubernetes.
📚 Key Learnings
- The one mental model
- The SDK surface area
- Three ways to author a component
- Parameters vs artifacts
- Signature patterns that matter
- The exercise pipeline, in full
- Compiling to IR YAML
- Uploading and running
- Runtime configuration
- Caching, for real
- Control flow
- Testing before you ship
- Troubleshooting
🧠 Learn here
In Day 27 you installed Kubeflow Pipelines and watched a DAG run. Today you stop being a spectator.
Read the full article on learnxops.com.
Topics: 100 Days of MLOps, MLOps, ML, Kubernetes, Kubeflow