Distributed JAX training: a beginner's guide for DevOps and MLOps engineers
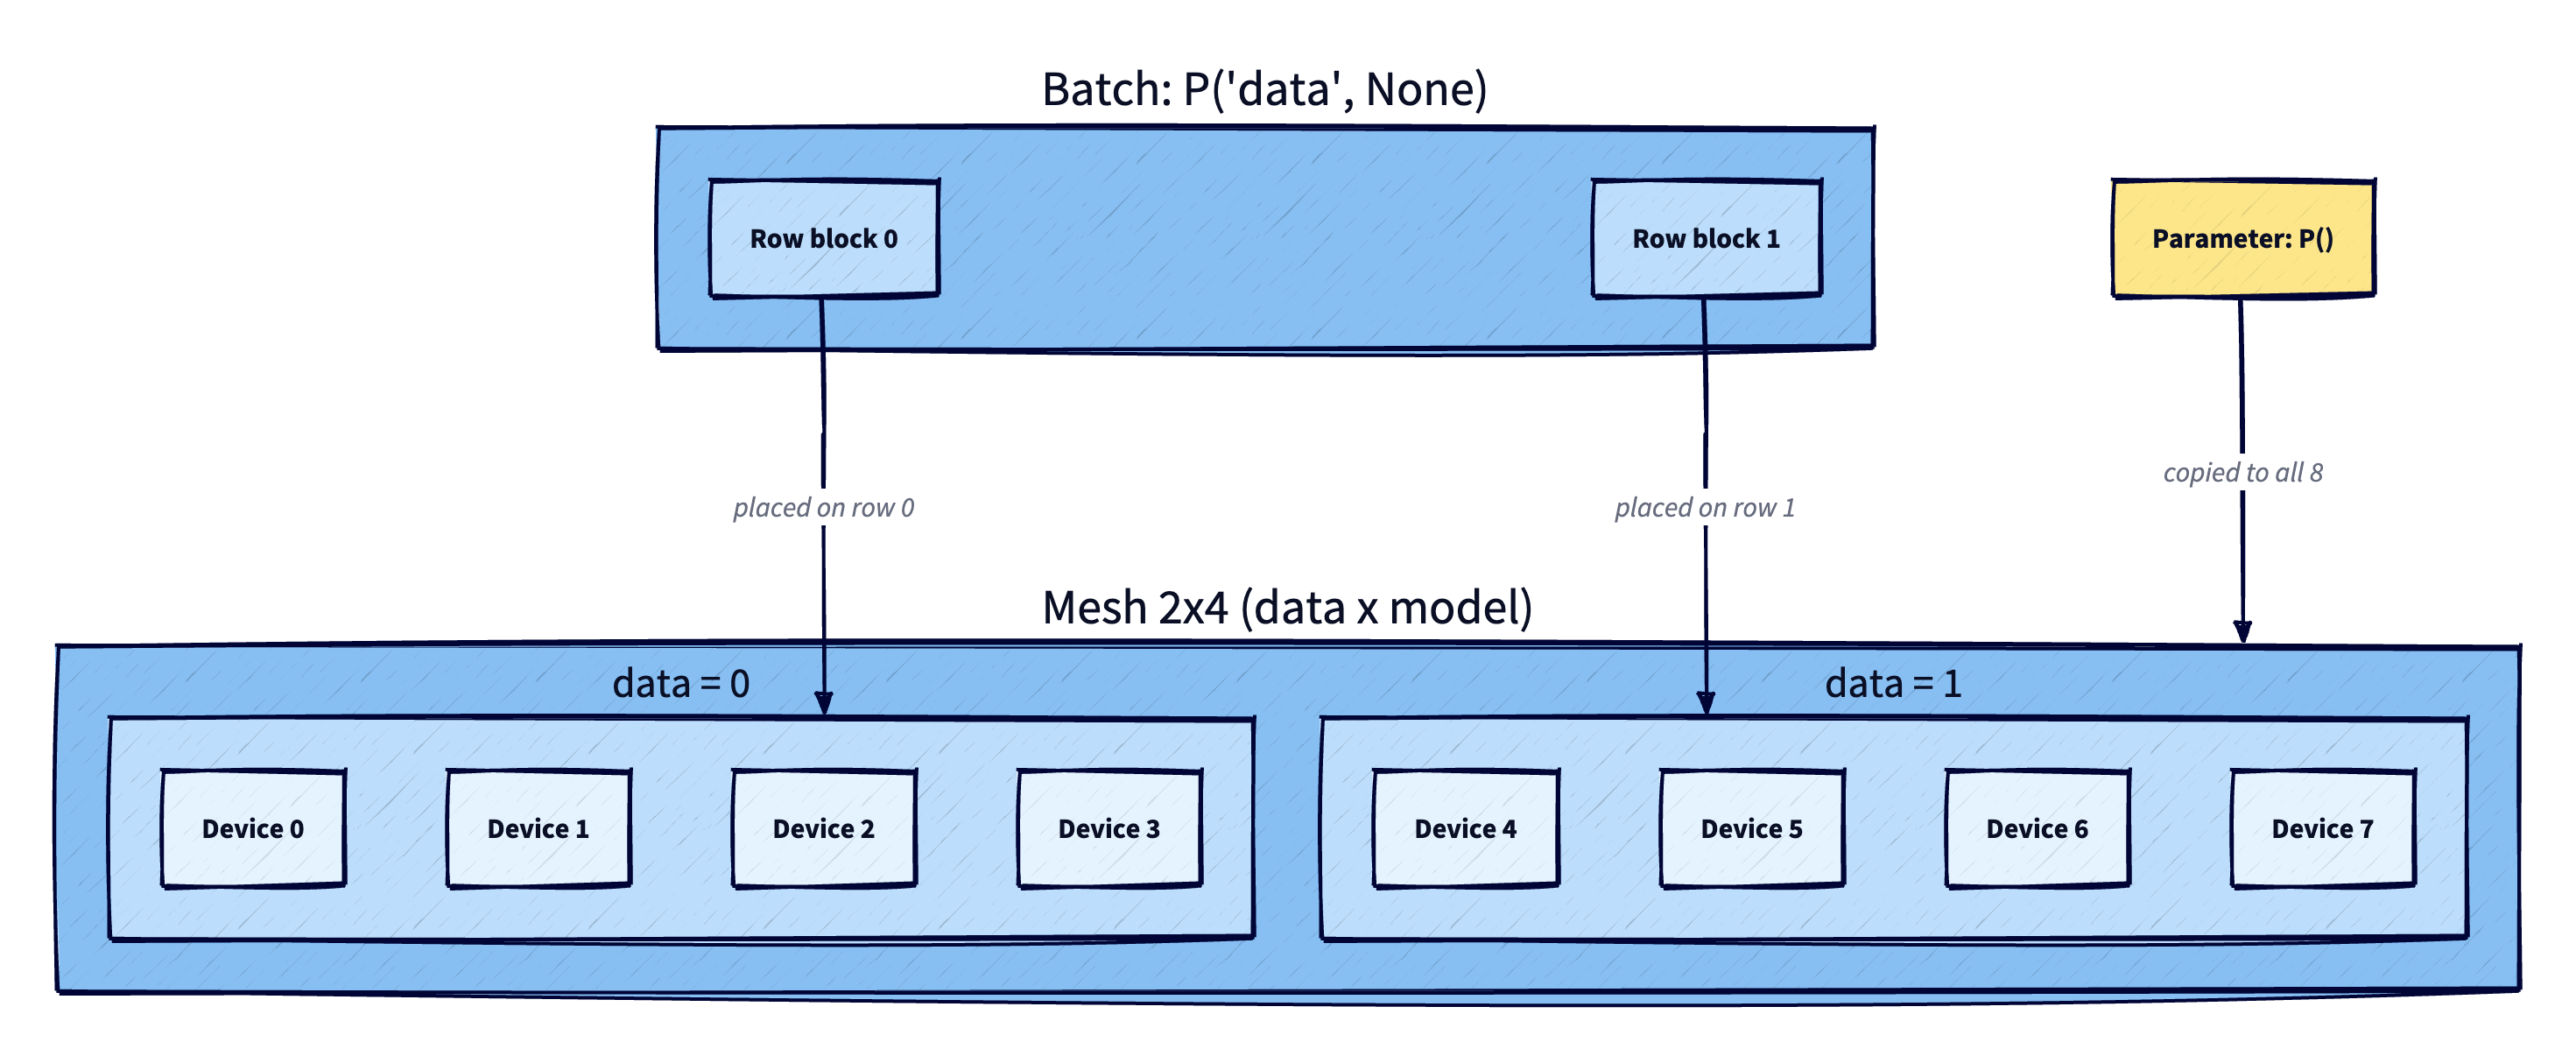
A hands-on introduction to training models across multiple GPUs or TPUs with JAX. You will learn how device meshes and sharding split data and parameters, how to scale a training step from one machine to several, and what operators need to set up and watch when running these jobs.
If you run infrastructure for machine learning teams, sooner or later someone will ask you to make a JAX training job use more than one accelerator. You need two things for that: a mental model of how JAX spreads work, and code that runs. Below, you'll first see how JAX differs from frameworks you may know and pick up its small vocabulary, then turn a single-device training step into a data-parallel one, shard the model itself, and scale out to several machines. The last sections are for operators: launching, configuration, checkpoints, monitoring, and the pitfalls that catch most people on a
Read the full article on LearnXops (free with a LearnXops account).