SageMaker Model Deployment & Endpoints
Take your trained machine learning models from the registry to production by deploying scalable, secure, and highly available real-time inference endpoints with Amazon SageMaker.
By Sandip Das · · 6 min read
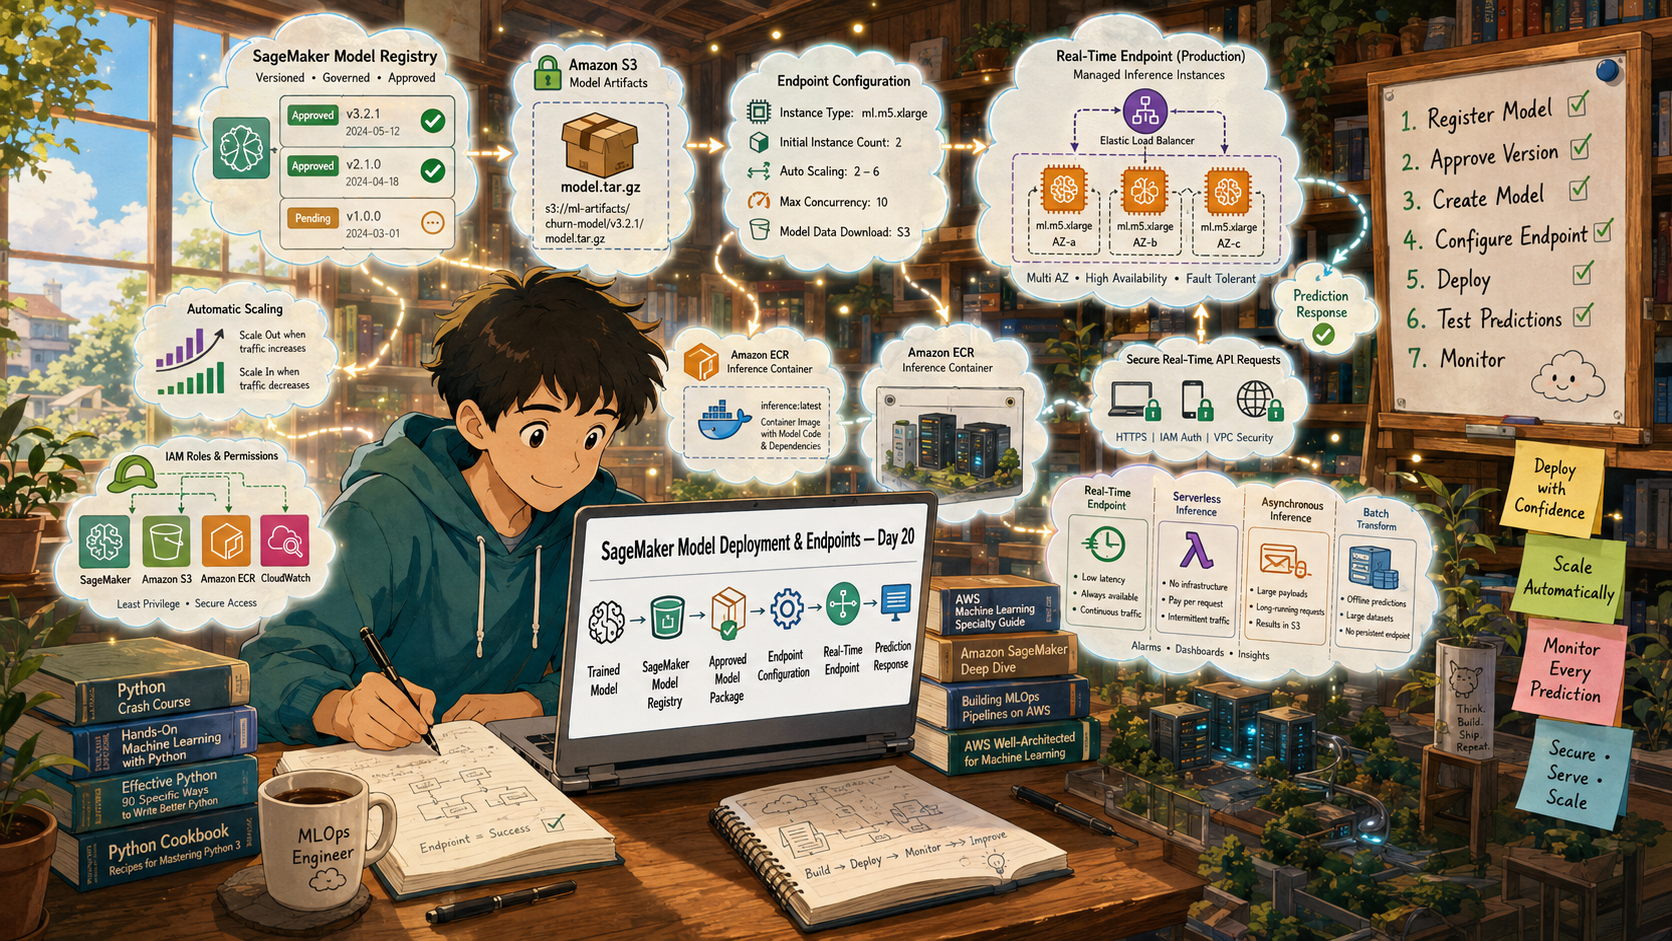
💡
Hey — It's Sandip Das 👋
Deploying machine learning models reliably is one of the most critical responsibilities of any MLOps engineer, and Amazon SageMaker simplifies this with managed model hosting, real-time endpoints, auto-scaling, and production-grade infrastructure.
Mastering SageMaker deployment enables you to deliver low-latency, highly available AI services while reducing operational complexity and accelerating the path from experimentation to production.
📚 Key Learnings
- The four deployment modes
- Two ways to deploy: SDK vs boto3
- Invoking the endpoint with boto3
- Choosing an instance type
- Cleanup — delete in reverse order
🧠 Learn here
Real-time endpoints are the SageMaker deployment mode you reach for when a client needs a prediction now, one request at a time, with low latency — a web app scoring a form submission, a fraud check at checkout. That's the classic online-ser
Read the full article on learnxops.com.
Topics: 100 Days of MLOps, MLOps, ML, Community, Python, MLflow, Cloud, AWS, GCP