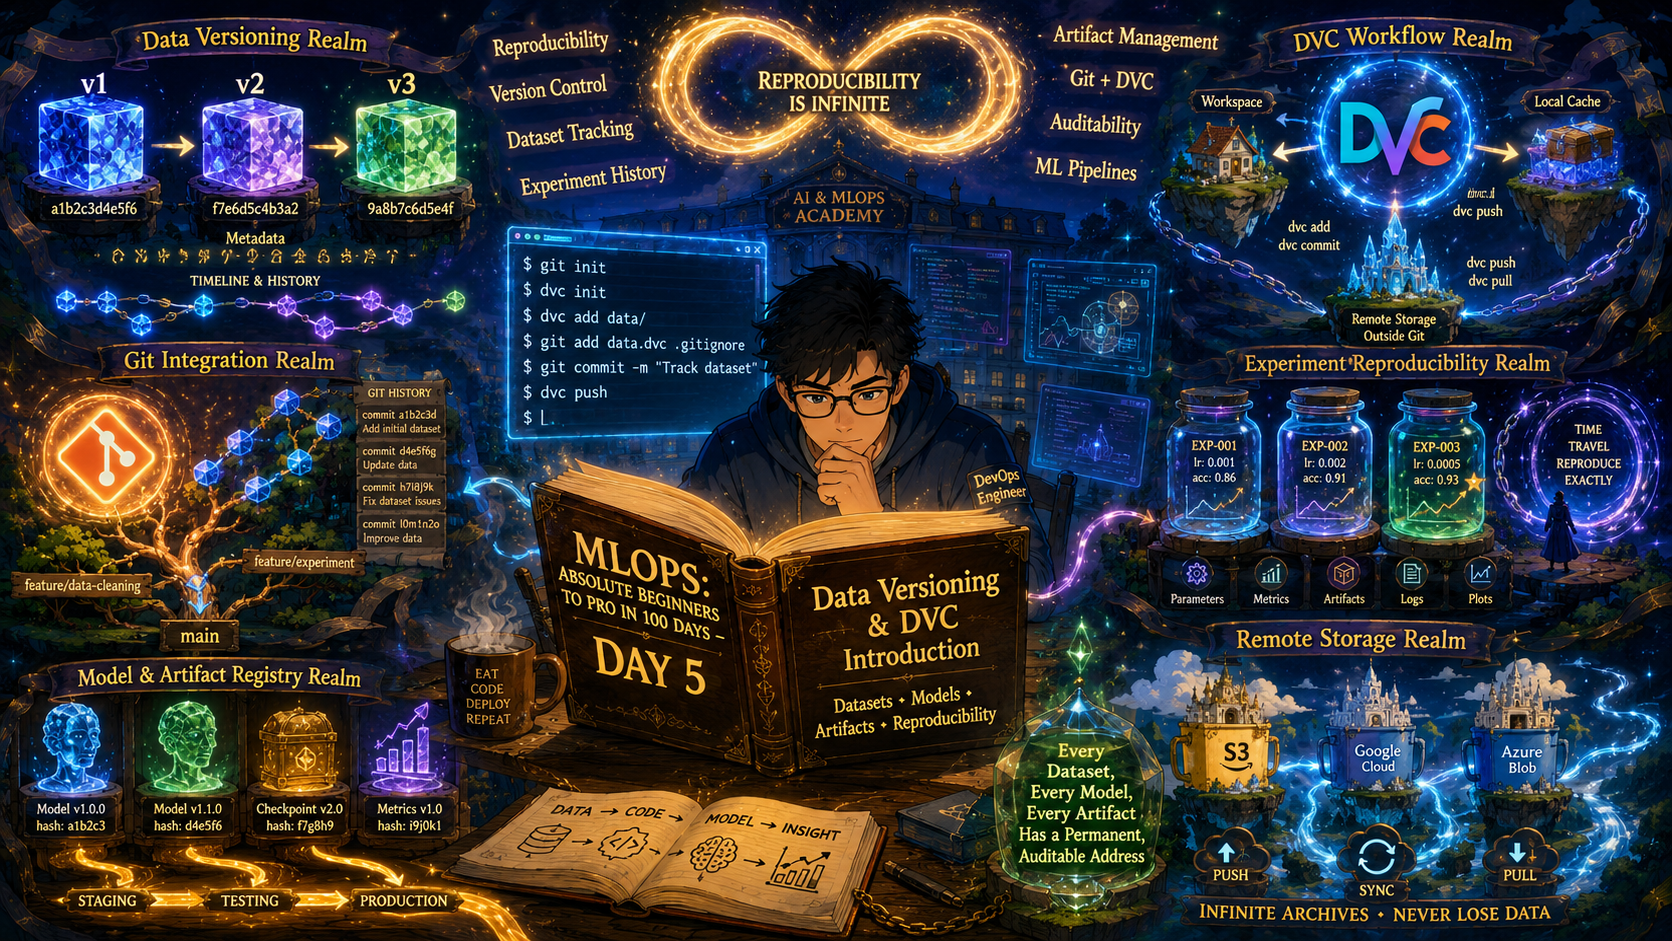
Data Versioning & DVC Introduction
Why your ML experiments are irreproducible without proper data versioning and how DVC pairs with Git to give every dataset, model, and artifact a permanent, auditable address.
By Sandip Das · · 14 min read
💡
Hey — It's Sandip Das 👋
We should learn data versioning because ML systems are only reliable when datasets and models are reproducible and traceable.
Understanding DVC and Git enables them to build auditable, production-grade pipelines with the same discipline used for infrastructure and application code.
We should learn data versioning because ML systems are only reliable when datasets and models are reproducible and traceable.
Understanding DVC and Git enables them to build auditable, production-grade pipelines with the same discipline used for infrastructure and application code.
📚 Key Learnings
- Why Data Versioning Matters
- Git vs DVC — The Fundamental Split
- DVC Core Concepts
- Architecture & How DVC Works
- The Core DVC Workflow
- Installation
- Hands-On Exercise (Full Walkthrough)
- Understanding the .dvc File
- Versioning Multiple Data Releases
- Remote Storage Options
- Essential DVC Command Reference
- Common Pitfalls
LearnXops Labs:
🧠 Learn here
Read the full article on learnxops.com.
Topics: 100 Days of MLOps, MLOps, ML, Community, Python, DVC